01Core reference
Docs
API Documentation
Complete reference for chat completions, streaming, tool calling, JSON schema validation, and rate-limit headers.
Developer ecosystem
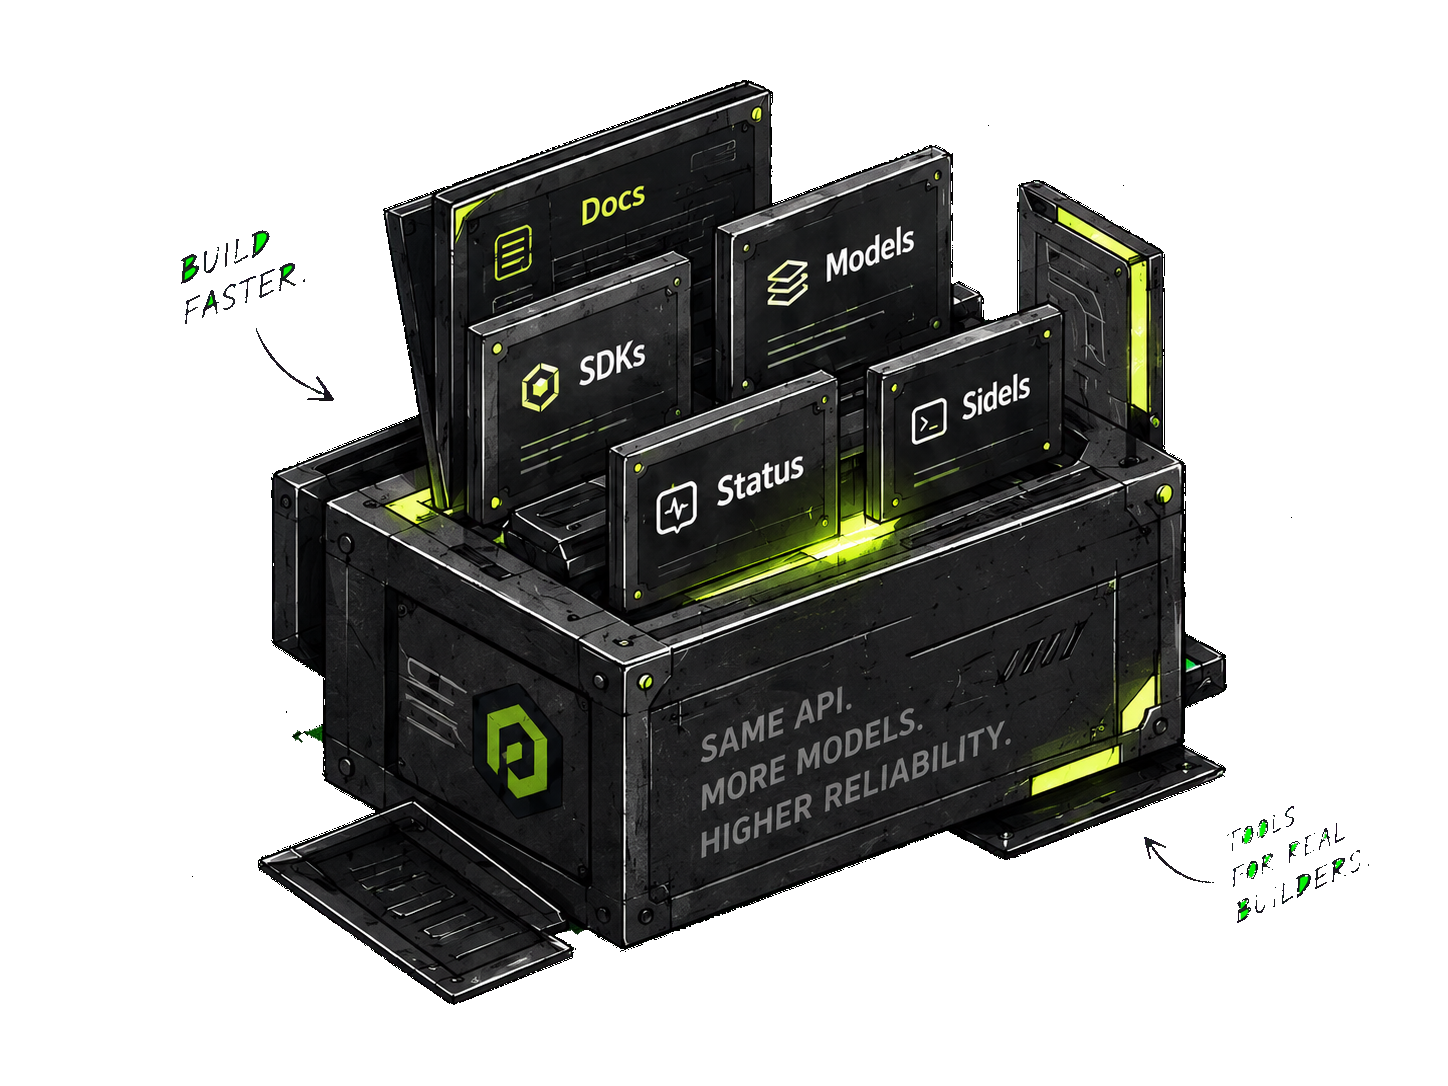
Everything you need to integrate, route, monitor, and scale with InferencePass. From the first request to a production incident, the useful context stays close.
Platform tooling
Useful reference material and live signals, organized around the work developers actually do.
Docs
Complete reference for chat completions, streaming, tool calling, JSON schema validation, and rate-limit headers.
Status
Current route availability, operational health checks, historical incident reports, and catalogue versions.
SDKs
TypeScript and Node.js client patterns plus the OpenAPI specification for generated clients.
Models
Review supported models, context limits, token basis calculations, and active upstream verification.
Playground
Run prompts against available models, compare results, inspect usage, and test tools live.
Security
Explore session controls, browser data policies, and the architectural boundaries behind the service.
One-line integration
Point an existing OpenAI client to the gateway and let the route handle provider selection and failover.
import OpenAI from "openai";

const client = new OpenAI({
  baseURL: "https://api.inferencepass.com/v1",
  apiKey: process.env.INFERENCEPASS_API_KEY,
});

const response = await client.chat.completions.create({
  model: "gpt-4o",
  messages: [{ role: "user", content: "Explain deterministic routing." }],
});